Almost everyone who starts programming ends up with a folder that looks like this: website_final, website_final_2, website_final_REALLY, website_old_do_not_delete. We had one too. Git is the answer to exactly that mess.
What is Git? Git is a free version control system that stores every change to your files as a traceable snapshot. You can always see who changed what and when, jump back to any earlier state, and safely work on several ideas in parallel. Git runs locally on your machine, needs no server and no account, and it is the tool that practically the entire software industry works with today.
In this article we explain Git so that it makes sense without prior knowledge: what actually happens internally when you “save”, what commits and branches really are, how Git differs from GitHub, and which mistakes we have made ourselves. All numbers come from our own measurements on October 17, 2026, on our server running Git 2.43.
Tech With Diego’s seven-minute overview (August 2025) is a quick visual primer. This article goes deeper into the “why”: once you understand what Git does behind the scenes, you make far fewer mistakes.
What Is Git — the short answer
If you only want to read five sentences, read these:
- Git is a version control system. It remembers the history of a project, file by file, change by change.
- A commit is a snapshot. You explicitly tell Git: “This state matters, remember it,” and add a short message.
- A branch is a side road. You can tinker with a new idea next to the working version without endangering it, then merge the idea in later or throw it away.
- Git is distributed. Every copy of a project contains the complete history. You work offline, and there is no server that everything depends on.
- Git is not GitHub. Git is the program on your computer. GitHub, GitLab and Codeberg are websites where people store and collaborate on Git projects.
The rest of this article explains why that is and what it means in everyday work.
Why do you need Git at all?
The honest answer: as long as you work alone on a single file, you don’t. As soon as any of the following applies, it quickly becomes indispensable:
- You want to undo changes, even days later. Ctrl+Z ends when you close the editor. Git never does.
- You want to know why something is the way it is. For every line of code, Git can tell you when it arrived, who wrote it and why (
git blameandgit log). - You work with other people. Two people edit the same file? Git combines both changes and only asks for help when both touched the same line.
- You want to experiment without fear. A branch costs nothing. If the experiment fails, you delete it.
- You want to deploy. Many hosting services (Vercel, Netlify, Cloudflare Pages, but also your own server) pull code straight from a Git repository. If you want to build that yourself, see our article on a Vercel alternative.
Git isn’t limited to code either. Anything made of text files benefits: configuration, documentation in Markdown, translations, even novels. This blog consists of MDX files. With large binary files such as videos or Photoshop documents, Git hits its limits; more on that later.
A very short history of Git
Git isn’t a company’s product; it was born out of an emergency. Until 2005, Linux kernel development used a commercial tool called BitKeeper, whose vendor ended free use for kernel developers in April 2005. Linus Torvalds, the creator of Linux, then wrote his own system within days. The goals were clear: fast, distributed, and it should be impossible to tamper with history unnoticed.
In July 2005 Torvalds handed maintenance over to Junio Hamano, who still maintains Git today. Git is licensed under GPLv2, so it’s free software and costs nothing. The name is British slang for an unpleasant person; Torvalds joked that he names all his projects after himself.
From 2008, GitHub brought Git to a broad audience, and Microsoft bought GitHub in 2018. By the 2010s at the latest, Git was the standard: in the 2022 Stack Overflow Developer Survey, more than 90 percent of respondents said they used Git. Older systems like Subversion (SVN) or CVS mostly survive in legacy projects.
How long such a history lasts is shown by our first measurement. We cloned the repository of the web framework Express:
git clone https://github.com/expressjs/express
cd express
git rev-list --count HEAD        # 6181
git log --reverse --format="%ad %an" --date=short | head -1
# 2009-06-26 visionmedia
git shortlog -sn HEAD | wc -l    # 398
6,181 commits by 398 different authors, the first one dated June 26, 2009. Every single one is contained in the copy on our server, and the whole package is just 12 MB. Seventeen years of development history, smaller than an average phone video.
How Git works: the three areas
The concept that confuses beginners the most is also the most important one: Git knows three places where a change can live.
- Working directory: your ordinary project folder. You edit files here with your editor. Git watches but doesn’t store anything yet.
- Staging area (also called the index): a kind of packing table. With
git addyou deliberately place the changes that should go into the next snapshot. - Repository: the archive in the hidden
.gitfolder.git committurns everything on the packing table into a permanent snapshot.
Why the extra step? Because you rarely change exactly one thing at a time. Maybe you fixed a bug and also corrected a typo in the README. The staging area lets you turn that into two clean commits instead of one “changed some stuff” commit. It feels clunky at first and becomes priceless later, when you search history for the cause of a bug.
The typical flow looks like this:
git status                  # what changed?
git add index.html          # put this file on the packing table
git commit -m "Fix navigation on mobile devices"
git log --oneline           # look at history
By the way, git status is the command we type most often. It’s essentially free: in our Express clone it took 8 milliseconds.
What is a commit, really? A look inside the .git folder
This is where it gets interesting, and where you understand why Git is so robust. We created an empty test project, wrote a file containing “Hallo Welt” (“Hello world”) and committed it. Then we asked Git to show us the raw commit:
git cat-file -p HEAD
# tree 635ac6d4113233f71fd5507d6e287c26bd841ef0
# author Test <t@t> 1792220497 +0000
# committer Test <t@t> 1792220497 +0000
#
# init

git cat-file -p HEAD^{tree}
# 100644 blob 636af6605bfd946e3d245d5086cf565336ad6383   a.txt
So a commit is a tiny text note: it points to a tree (a directory), contains author, time and message, and every later commit also points to its predecessor (parent). The tree points to blobs, which hold the actual file contents.
Every one of these objects is named after a checksum of its content. You can verify that directly:
git hash-object a.txt
# 636af6605bfd946e3d245d5086cf565336ad6383
The same string as above. Three properties follow from this that are worth knowing:
- Same content, same object. Git stores identical files only once. We then copied the file 1,000 times and committed all copies. The number of objects went from 3 to exactly 5: one new tree, one new commit, but not a single new blob. The
.gitfolder grew from 172 to 256 KB, almost entirely because of the longer file list. - History is tamper-evident. Because each commit contains its predecessor’s checksum, any later change would alter all following checksums. Manipulating history unnoticed isn’t possible.
- Git stores snapshots, not differences. Conceptually, every commit is a complete image of the project. Git still saves space by reusing unchanged blobs and compressing objects into so-called packfiles.
Git traditionally uses SHA-1 for these checksums. Since version 2.29 (2020) SHA-256 is optionally available, and the switch is planned as the long-term default. For your daily work it makes no difference.
What is a branch? A 41-byte note
In older systems like SVN, a branch created a full copy of the project. In Git, a branch is almost ridiculously small: a file containing a single commit ID.
cat .git/refs/heads/b1
# 27263e8e7e16b0aea861b2d35bb9fd962ea0933d
wc -c .git/refs/heads/b1
# 41 .git/refs/heads/b1
41 bytes: 40 characters of checksum plus a newline. That’s all a branch is. We created 100 branches in a loop, which took 0.22 seconds in total. That’s why in Git it’s perfectly normal to create a branch for every little task.
The usual flow:
git switch -c new-homepage      # create branch and switch to it
# ... work, commit ...
git switch main                 # back to the main line
git merge new-homepage          # bring the work in
git branch -d new-homepage      # throw the note away
main (formerly usually master) is just a convention, not a special branch. New repositories get whatever name you set in init.defaultBranch.
What happens in a merge conflict?
Conflicts sound scary and rarely are. They only occur when two branches changed the same line differently. We reproduced one: on main the file said “Preis: 9 Euro”, on a feature branch “Preis: 12 Euro”. On merge, Git said:
Auto-merging p.txt
CONFLICT (content): Merge conflict in p.txt
Automatic merge failed; fix conflicts and then commit the result.
And the file contained both versions side by side:
<<<<<<< HEAD
Preis: 9 Euro
=======
Preis: 12 Euro
>>>>>>> feature
Git doesn’t guess. It stops and leaves the decision to you. You delete the markers, keep the right version, and finish with git add and git commit. If you get cold feet, git merge --abort puts everything back the way it was. We tested that: no data loss, no leftovers.
Git is distributed — and why that matters
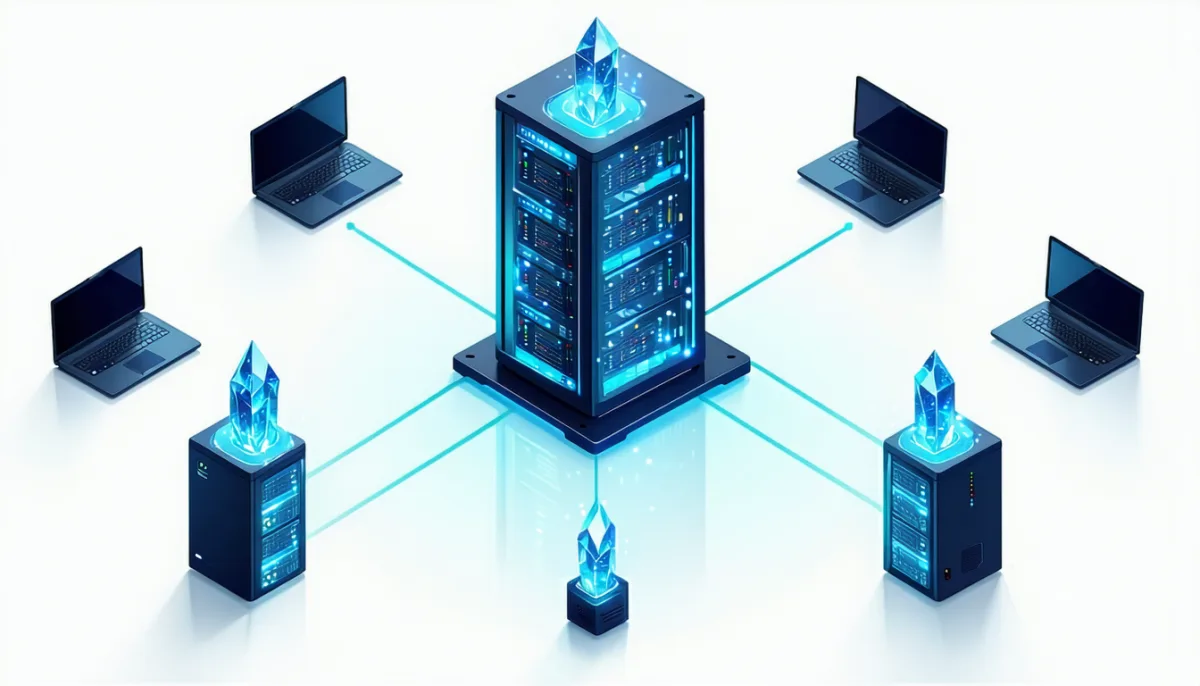
Older systems had a central server holding the history. If it went down, nobody could commit. With Git, every copy has the complete history. Your laptop, your colleague’s laptop, the server, GitHub: all are equal. A “remote” is simply another copy you exchange commits with.
The commands:
git clone <url>   # get a full copy
git pull          # fetch new commits from the remote and integrate them
git push          # send your commits to the remote
The exchange usually runs over HTTPS or SSH. For GitHub and your own server we recommend SSH with a key instead of a password; our guide generate an SSH key shows how.
Because everything is local, Git is very fast. git log across all 6,181 Express commits took 44 milliseconds for us. And if you don’t need history at all, you can clone shallowly:
| Variant | Command | Time | .git size |
|---|---|---|---|
| Full clone | git clone …/express | 1.00 s | 12 MB |
| Shallow clone | git clone --depth 1 …/express | 0.55 s | 392 KB |
The shallow clone is about 30 times smaller. Ideal for CI pipelines or a quick deployment; for daily work you want the full history.
Git vs. GitHub: the difference
This is the most common mix-up of all, so let’s be very clear:
| Git | GitHub (GitLab, Codeberg …) | |
|---|---|---|
| What is it? | A program | A website / platform |
| Where does it run? | On your computer | On the provider’s servers |
| Does it cost money? | No, free software (GPLv2) | Basics free, team features often paid |
| Needs internet? | No | Yes |
| What for? | Managing versions | Sharing repositories, pull requests, issues, CI/CD, wiki |
| Who’s behind it? | Open-source community | GitHub = Microsoft, GitLab = GitLab Inc., Codeberg = non-profit association |
You can use Git your whole life without GitHub. The reverse isn’t true: at its core GitHub is a hosting service for Git repositories with lots of collaboration tools on top. The most important one is the pull request (GitLab calls it a “merge request”): someone proposes merging a branch, others read the code, comment and approve.
If you’d rather not keep your projects with a US corporation, there are good alternatives. Codeberg is a non-profit based in Berlin that runs on the Forgejo software. Forgejo and Gitea can also be self-hosted, for example with Docker on your own server. And for very small setups, a bare repository on a server you reach via SSH is enough. Git doesn’t need more than that.
GitHub’s own beginner introduction (May 2024, so older than our usual six-month window). We include it because it’s the official walkthrough of installing, configuring, staging, committing and branching, and none of those basics have changed since.
Installing Git and the first five minutes
Git is already present on macOS (via the Xcode command line tools) and on most Linux systems, or one command away:
# Debian / Ubuntu
sudo apt install git
# Fedora
sudo dnf install git
# macOS
xcode-select --install
# Windows: installer from git-scm.com, or
winget install --id Git.Git
Then tell Git once who you are. This information goes into every commit:
git config --global user.name "Your Name"
git config --global user.email "you@example.com"
git config --global init.defaultBranch main
And then your first repository:
mkdir my-project && cd my-project
git init
echo "# My Project" > README.md
git add README.md
git commit -m "First commit"
git log
That’s it. You now have a fully featured repository with no account, no server and no internet. Whether you type commands in a terminal or use a GUI (VS Code has Git built in, and there are GitHub Desktop, GitKraken, Sourcetree, or lazygit in the terminal) is a matter of taste. We recommend learning the core commands in the terminal once, because then every GUI makes sense.
The .gitignore file
Not everything belongs in the repository. Dependencies (node_modules), build output (dist), log files and above all credentials (.env) are excluded with a file called .gitignore:
node_modules/
dist/
*.log
.env
This isn’t optional. The next section shows why.
Mistakes we’ve made ourselves
Git is forgiving, but not all-knowing. We learned these three things in practice, some of them the hard way.
1. “Deleted” doesn’t mean deleted in Git
In our test we deliberately committed a .env file containing a key and removed it again in the next commit. It was gone from the project folder. Not from history:
git log --all -p -S geheim123 --format="%h %s"
# 9ebcff1 env weg
# -API_KEY=geheim123
# de822ef env
# +API_KEY=geheim123
Anyone who clones the repository can find the key with exactly this one command. Automated scanners search public repositories around the clock for such finds. A password that was pushed once must be considered burned. The only safe response: revoke the key with the provider immediately and generate a new one. Cleaning history afterwards (with git filter-repo) is possible as an extra step, but it doesn’t replace revocation, because copies may already exist elsewhere.
2. Git is not a backup
Because every copy contains the whole history, it’s tempting to think Git already is a backup. That’s only half true. Git saves what you commit, not what’s in .gitignore, no databases, no uploaded images, no server configuration outside the repository. And a git push --force can overwrite history on the remote. For real protection you need a dedicated strategy, such as the 3-2-1 backup rule. Git is one building block, not the replacement.
3. Almost nothing is truly lost: the reflog
The good news to finish: locally, it’s very hard to lose committed work in Git. In our test we “threw away” the last commit with git reset --hard HEAD~1. The file showed the old price again. But Git keeps a diary of every movement:
git reflog
# b2e6791 HEAD@{0}: reset: moving to HEAD~1
# bd4565e HEAD@{1}: reset: moving to HEAD
# bd4565e HEAD@{2}: commit: c
git reset --hard HEAD@{1}
After that, the “lost” commit was back. By default the reflog keeps such entries for at least 30 days. What was never committed, however, Git can’t rescue. So commit too often rather than too rarely.
Where Git reaches its limits
Git is excellent for text and mediocre for everything else.
- Large binary files. Videos, 3D models or large images can’t be meaningfully compared line by line. Every new version is stored in full and the repository bloats. For games, design and media there’s Git LFS (Large File Storage), which moves large files out, or specialised systems like Perforce.
- The learning curve. You learn the core commands in an afternoon. Rebase, cherry-pick, submodules and cleaning up a messed-up history take longer. Command names grew historically and aren’t always logical;
git checkout, for example, does quite different things, which is why the clearergit switchandgit restorenow exist. - Huge monorepos. With millions of files even Git slows down. Companies like Microsoft built extensions for this (Scalar is now part of Git). For normal projects it doesn’t matter; our own repositories with a few hundred files have
.gitfolders in the single-digit megabytes.
Git vs. other version control systems
| System | Type | Relevant today for |
|---|---|---|
| Git | distributed | Practically everything: open source, companies, web, apps |
| Subversion (SVN) | centralised | Legacy projects, some agencies and enterprises |
| Mercurial | distributed | Few projects; Bitbucket dropped support in 2020 |
| Perforce (Helix Core) | centralised | Game studios with huge binary assets |
| Fossil | distributed | Niche (e.g. SQLite), includes wiki and tickets |
If you’re starting out, there’s really no decision to make: learn Git. Nearly every job ad, tutorial, tool and hosting platform assumes it.
A workflow that’s enough for most people
There are thick books about Git workflows. For individuals and small teams, this one is enough:
mainalways works. Whatever is there can go live.- Every task gets its own branch, e.g.
fix/login-buttonorfeature/newsletter. - Small commits with clear messages. Rule of thumb: the message describes what the commit does, in the imperative: “Enlarge login button on mobile”, not “changes”.
- Get a review before merging (pull request) if there are several of you. If you’re alone, at least read
git diff mainyourself. - Merge, delete the branch, deploy.
That’s how we work too. This blog, our analytics project and most of our server services live in Git repositories, and in many cases deployment is nothing more than a git pull on the server followed by a restart. How to prepare your own server for that is described in Linux server setup.
Conclusion: What is Git — and is it worth learning?
Git is a project’s memory. It stores every deliberate checkpoint as an immutable snapshot, lets you experiment safely and makes collaboration practical in the first place. Our measurements show how lightweight it is: 17 years of history from almost 400 people in 12 MB, a branch in 41 bytes, git status in 8 milliseconds.
Anyone who programs, builds websites or runs servers can’t avoid Git, and that’s a good thing. The basics (init, add, commit, log, switch, merge, push, pull) can be learned in an afternoon. Remember three sentences alongside them: Git is not GitHub. Git is not a backup. And whatever was committed once stays in history. That protects you from the most common mistakes.
Frequently asked questions about Git
What is Git in simple terms?
Git is a program that remembers every saved version of your project files. You can always see what changed and when, return to an old state and work on different ideas in parallel. Think of it as an extremely thorough “undo” feature that never forgets and also works in a team.
What is the difference between Git and GitHub?
Git is the software on your computer that manages versions. GitHub is a website where you store, share and collaborate on Git repositories, with extras like pull requests and issues. Git works entirely without GitHub; GitHub doesn’t work without Git. Alternatives to GitHub include GitLab, Codeberg or a self-hosted Forgejo.
Is Git free?
Yes. Git is free software under GPLv2 and costs nothing, including for commercial use. Costs can only arise with hosting platforms, for example for private team features on GitHub or GitLab. A repository on your own computer or server is always free.
Who invented Git?
Linus Torvalds, the creator of Linux, wrote Git in April 2005 after kernel developers could no longer use the BitKeeper tool for free. Since July 2005 Git has been maintained by Junio Hamano and developed further by a large open-source community.
What is a repository?
A repository (“repo”) is a project folder managed by Git. Technically it’s your normal folder plus a hidden .git subfolder that holds the entire history: all commits, branches and file versions. If you delete .git, only the current state of the files remains.
What is a commit?
A commit is a saved snapshot of your project with author, timestamp and a short description. Each commit points to its predecessor, forming an unbroken chain. It’s identified by a unique checksum like bd4565e, which you can use to return to exactly that state at any time.
What is a branch in Git?
A branch is a side road in history where you can work without changing the main line. Technically it’s just a pointer to a commit, in our measurement a 41-byte file. That’s why branches in Git are cheap and fast, and why people create one for every task.
Do I need Git if I code alone?
Yes, we’d always recommend it. Even alone you’ll want to restore old states, try experiments safely and understand why you built something a certain way three months ago. Then there’s deployment: many hosting services expect a Git repository. The effort is minimal; a git init is enough to start.
Is Git a backup?
Only partly. Git saves the files you commit, and every cloned copy contains the full history. But it doesn’t save databases, ignored files or server configuration, and a force push can overwrite history on the remote. Git is one part of a backup strategy, not a replacement for one.
How long does it take to learn Git?
You can learn the everyday commands (init, add, commit, status, log, switch, merge, push, pull) in an afternoon. Becoming confident with conflicts, rebase and fixing mistakes takes a few weeks of real project work. More important than any course is using Git in every one of your own projects from now on.
Can I use Git for Word documents or images?
Technically yes, but it’s most useful for text files. With binary files like Word documents, images or videos, Git can’t show differences and stores every version in full, so the repository grows quickly. For large media files there’s the Git LFS extension.